Jekyll2026-10-09T07:46:22+00:00https://edihasaj.com/atom.xmlEdi HasajSoftware, AI and Thinking.Edi HasajPlaying with one-pass decision models2026-10-09T07:00:00+00:002026-10-09T07:00:00+00:00https://edihasaj.com/playing-with-one-pass-decision-modelsAfter writing about Jev, I started playing with the same question: what happens if a model only needs to choose an answer?
A lot of the calls in my agent workflows have that shape. Which team should handle this request? Does this change need a closer review? The answer is a choice from a small menu. I wanted to try something different from asking a language model to write JSON and then parsing it.
The first version used a frozen sentence encoder and a small trained scorer. The idea was to encode the context once, then score the possible answers against it. I compared that with similarity scoring and existing classifiers.
It worked well on the banking categories the scorer had seen during training. Categories it had never seen were a different story. With all 77 banking labels competing, the trained scorer got only 27.6% of the unseen-category cases right. The simple similarity baseline got 58.2%.
That was an early lesson: teaching the model a set of familiar choices did not make it good at arbitrary new choices.
Trying a different base
Later I adapted Decider 4B, a Qwen3.5-based model that scores typed answer options in one forward pass. This is the basis of the published Surebranch checkpoint. It is not an encoder-only model, even though the earlier experiment was built around an encoder.
I tried teaching it code decisions. Given a Python program and its tests, does a particular assertion pass? Does the whole suite pass? How many tests pass?
For the training labels, the programs were actually executed. At inference, the model only reads the code and scores the choices. It does not run the program. I mixed general decisions into training to try to improve the code answers without losing the base model’s broader abilities.
What came back
The published weights were checked on 250 Python programs, each executed twice to verify the labels. Asking the questions separately gave these development results:
Question
Accuracy
How many tests pass?
46.8%
Does the whole suite pass?
76.8%
Does one selected assertion pass?
84.4%
Those cases were used during model selection. They are not an independent final test.
Asking all twelve questions together gave 82% accuracy across 2,500 individual assertions. But it detected only 203 of the 555 failing assertions. The overall accuracy looked much better than its ability to catch failures, which is the part I would care about in a review tool.
Question order could also change the answers. Returning a valid probability for every option does not mean those probabilities are reliable enough to act on.
Where I left it
I ended the experiment on 2 October. No candidate passed fresh production qualification, and I did not establish that this checkpoint matches Jev or meets a particular serving price.
The model card has the loading example, measured results and limitations. The weights are there for people who want to play with the approach. The training code and datasets remain private.
What I wanted to explore was a different way to use a model: read the context, score the available answers, and stop there. Surebranch gave me something concrete to try, including a few results that looked good until I asked a more useful question about them.
]]>Edi HasajMy AI playbook2026-09-20T12:00:00+00:002026-09-20T12:00:00+00:00https://edihasaj.com/my-ai-playbookPeople ask me how I use AI. They expect a prompt. It is not a prompt, it is a setup. Here it is, the short version.
One file of rules
Every agent I run reads the same file first. Claude Code, Codex, whatever comes next. The file is public, it is called AGENTS.md, and it lives in one repo with the skills and the commands. Everything else links to it. I learned the hard way that if you keep two copies of a rule, one of them drifts and then breaks quietly.
The file is boring on purpose. Talk short. Use the repo’s package manager, dont swap it. Commit with the helper that only stages the files you name. Never delete, move to trash. Read the docs before you touch code. If CI is red, fix it until it is green. Verify end to end, and if you cant, say exactly what is missing.
That last one is the most important rule I have. An agent that says “should work” is the one that costs me the afternoon.
Tools built for agents
Most tools are built for a person with a mouse. Agents dont have a mouse. So a lot of what I built the last year is just giving them hands.
guiport lets an agent see and click a real desktop app. It reads the accesibility tree, finds the button, clicks it, types, and can save that flow as a test. Playwright but for Mac apps, basically.
abx is a browser with a command line. Open a page, read it, click, fill a form, no screenshots needed most of the time.
shotport is for when pixels are actually needed. It grabs the text first, and only spends tokens on the image if you ask. Screenshots are expensive for an agent and most of the time the text is enough.
vmlab is one command to run something on any machine. Docker box, Linux VM, Windows VM, a phone, a simulator. It spins the machine up, runs the thing, collects the evidence, and shuts it down so nothing keeps billing.
None of these started as products. Each one exists because an agent got stuck on something I would do in two seconds.
The pipeline that ships
When I want a change, I dont open a chat. I point shipyard at a repo and a task. A Jira key, a GitHub issue, or just a sentence.
It plans, makes a branch in the repos convention, does the work, runs lint and types and tests, runs a security review, then a second code review, writes the PR description, and stops. For client work it stops PR ready and I push. For my own stuff it opens the PR.
The agent cannot skip a gate. That is the whole design. I dont read most of the code anymore. I read the gates and I read the PR text like a colleague wrote it.
Sometimes I run many of these at once. A tmux grid with 32 panes, a queue of tasks, and each pane picks the next one. After a reboot a script finds the sessions and puts them back. It sounds like a lot, it is actually calmer than one chat window.
Who checks the work
This is the part people skip. The agent finishing is not the same as the thing working.
Two systems check. Probeport takes a change and tries to prove it. It reads the diff, runs the native gates, then actually uses the feature through the closest real surface: the browser with abx, the desktop with guiport, another OS with vmlab. Small models do the poking, a bigger model argues with their evidence and decides if the exact revision works. The verdict comes back with screenshots and logs attached, not with “looks fine”.
Autoreview watches the other direction. It reads feedback, bug boards and GitHub issues, maps each one to a repo, and writes a dry run report of what it would do. Nothing happens until I enable a project and say execute. Then it can hand the work to shipyard, and the loop closes: feedback in, verified PR out.
Memory
Agents forget. The first fix was a markdown file of rules, which grew until nobody read it, me included. The fix now is Recall. When I correct an agent in a conversation, a hook catches it, checks if it is a real rule or a one off, and stores it. Next session, on any machine, the relevant ones get injected. I said “no em dashes” once. Every agent knows it now.
What I would tell you
Put the rules in one place. Give the agent tools that return text. Never let the agent decide if the gate passed. Have something else check the work before you do. Keep memory small and filtered.
And keep yourself in the loop where money, customers, or deleting things are involved. Everywhere else, get out of the way. The agents are better at the work than at knowing when it is done, so build for the second part.
]]>Edi HasajJev is a smart if statement, and that is the point2026-09-18T18:00:00+00:002026-09-18T18:00:00+00:00https://edihasaj.com/jev-is-a-smart-if-statement-and-that-is-the-pointLook at what a real agent pipeline actually asks a model, call by call. Is this diff risky? Which team does this ticket belong to? Is this correction worth remembering? Should this tool call be allowed? Does this search result answer the question?
Almost none of those need a paragraph. They need a yes, a choice, or a score. For the last year we have been asking a frontier language model, waiting a second or two, paying for the tokens, parsing JSON out of prose, and retrying when it came back malformed. It worked. It was also the wrong tool, and everyone building agents knew it.
On 15 September TypeSafe AI came out of stealth with Jev, and their own description is the best one: a smart if statement.
What it is
Jev is not a language model. It cannot write text at all. You give it state, either text or JSON, and typed questions with a fixed answer space. Three kinds: yes or no, a choice from options, or a score on a scale. It returns the answer, a probability for every option, and a confidence value. That is the whole API.
Because the answer space is declared up front, it cannot return something outside it. No malformed JSON, no “As an AI” preamble, no hallucinated fourth option. TypeSafe calls this a System One model and trained it with a method they call RLCD, reinforcement learning for calibrated decisions, so the probabilities are supposed to match how often the answer is actually right.
Numbers from their launch: most calls land around 100 milliseconds, input costs $0.042 per million tokens and output is free. They claim around 200 times faster and 400 times cheaper than a frontier LLM on classification. Those are launch-week vendor claims, so treat them as such. Even if they are off by ten, the gap is still a different category.
Why this matters more than the model
The thing I care about is not Jev. It is the split.
We have been using one kind of model for two different jobs. Generation, where you want a paragraph and some creativity is fine. And decision, where you want the same answer every time for the same input, fast, and with a number that tells you how sure it is. Frontier LLMs are great at the first and a wasteful, jittery fit for the second.
A decision model with typed outputs and calibrated confidence changes what you can build. You can set a threshold. Above 0.95, act. Below, escalate to a bigger model or a person. That is a normal engineering control, and until now it was hard to get from an LLM because the confidence was vibes.
Deterministic is the wrong word, strictly. It is still a model and it can still be wrong. But the shape of the output is deterministic, and that removes most of the failure modes I actually hit in production: parse errors, drift between runs, and a bill that scales with how chatty the model felt.
In my agent pipeline there is a security review and a code review gate. The first question each one answers is “does this diff touch anything risky.” Yes or no, with a confidence I can threshold. Recall, my memory layer for agents, has a quality gate that decides whether a correction is a durable rule or a one-off. Same shape. Oktapod decides whether a tool call needs approval. Same shape.
Every one of those is a frontier model call today. Each one is a candidate for a 100 millisecond typed answer.
Where it stops
It is three days old, and the “cannot hallucinate” line in the marketing is doing more work than it should. The output shape cannot be wrong. The answer still can. It cannot do arithmetic, compare dates, write code, or reason in more than one hop, and TypeSafe says so themselves. Text only, no images.
So it is not a replacement for the language model. It is the thing you put in front of it. The LLM still writes the fix, the reply, the summary. Jev decides whether to, which one, and how sure it is.
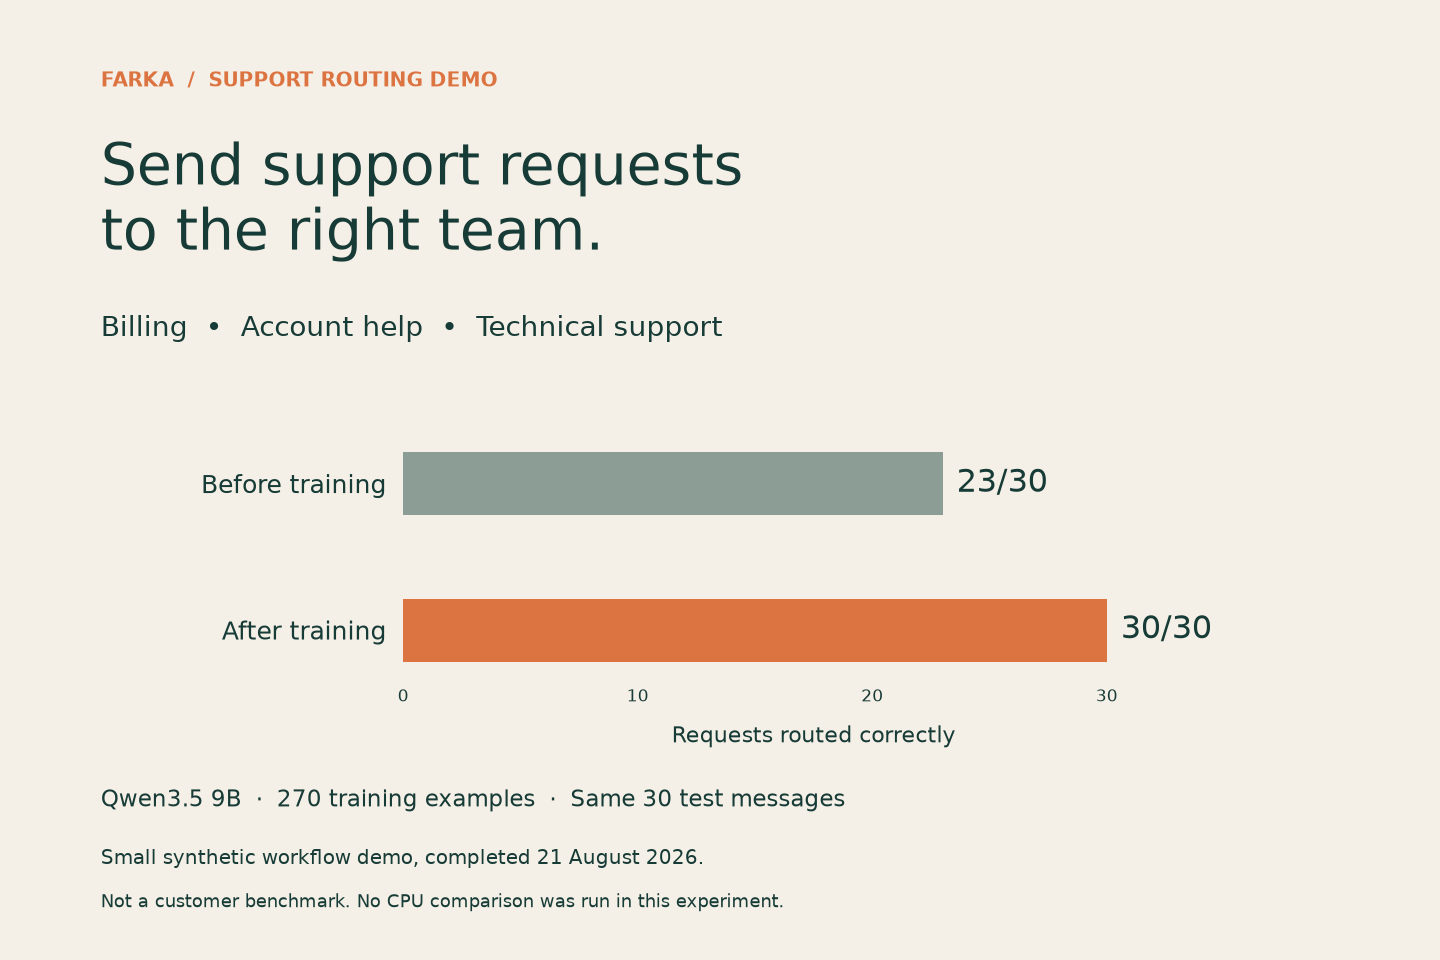
For the routing case I already have an alternative: a small fine-tuned model on my own hardware that got 30 of 30 on the test set. When the data cannot leave, that stays the right choice. For everything else, a lot of my if statements are going to move.
The bigger point
For a year the community built agents on the assumption that every decision costs a language model call. Whole architectures grew around minimising those calls: caching, batching, prompt compression, cheaper models for cheaper questions. A decision model makes most of that unnecessary. The decision becomes as cheap as a database lookup, and you stop designing around its cost.
That is the part I think people will look back on. Not the model. The moment “ask the LLM” and “ask a decision model” became two different calls.
]]>Edi HasajWhy LLM writing does not feel human2026-09-18T00:00:00+00:002026-09-18T00:00:00+00:00https://edihasaj.com/why-llm-writing-does-not-feel-humanYou can tell. Someone pastes a paragraph into a chat, a pull request, a support reply, and within a sentence you know a model wrote it. Not because of a wrong fact or a bad argument. It just does not feel like a person.
Two years ago people blamed the words. “Delve”, “tapestry”, “leverage”. I checked that with the current models and the words are gone. I asked Claude Sonnet, Claude Opus and two Codex models to write 96 short everyday and engineering texts, then compared them with 72,000 words of commit messages written by engineers before ChatGPT. Not one “delve”. The models’ vocabulary is even plainer than the engineers’.
And still every answer reads like a model. So it was never the words.
What actually feels off
Read the human commit messages and the model answers side by side and the difference is not in any single line. It is in the shape.
The humans are uneven. They start mid-thought, they say “otherwise” when they are weighing a case, they leave a sentence hanging, they skip the introduction because the reader already has context. They write for one specific person on one specific day.
The models are even. Every answer has the same rhythm: a framing line, a body with the same punctuation, a soft close. All four models, from two different companies, share that rhythm. In my sample the em dash appears in most answers from every model and zero times in the human text. Eleven answers open with “Here’s”. The humans never did. Those are just the parts I could count. The rest of the feeling is the same thing at a level I cannot count: the same shape, every time, for everyone.
Why I think this happens
A model learns what writing is from its data. For the first generation that data was mostly people. Since then a growing share of what goes into training is written by models: synthetic examples, model-rewritten documents, answers rated by other models. It is cheap, clean and endless, so labs use more of it every year.
Model-written data has no specific person and no specific day behind it. It is the average of every text, and the average has one shape. When a model learns from that, it learns the shape more firmly than the last one did. The words got fixed because “delve” was a public joke and easy to filter. The shape did not get fixed because nobody named it, and because the data itself keeps teaching it.
That is my point. The reason LLM writing does not feel human is not a style setting. It is where the writing came from.
What would change it
More real data from real contexts, and less of the synthetic kind. Companies sit on decades of text written by actual people to actual people: tickets, reviews, internal docs, support threads, engineering discussions. That is messy and specific and it belongs to someone, so it is harder to use than a generated dataset. It is also the only kind of text that carries the thing the models are missing. Quality here means provenance: written by a person, for a reason, in a place. A model trained on more of that and less of its own output would sound less like every other model.
I cannot see inside the labs, so this is a reading, not a proof. The small test that started it is in the experiments folder of this site, if you want to check the numbers or run it against a newer model.
This post contains no em dashes. It took editing.
]]>Edi HasajTeaching a 9B model to route support requests2026-09-13T00:00:00+00:002026-09-13T00:00:00+00:00https://edihasaj.com/farka-qwen-support-routingI’m building Farka to make it easier to teach a model a specific job: give it examples, train it, compare what changed, and export the result.
One small demo starts with a familiar problem. A support request arrives. Which team should handle it?
Give the model a clear job
The task had three destinations: billing, account help and technical support. The model chose a team. It did not answer the customer, issue a refund or change an account.
We fine-tuned Qwen3.5 9B using 270 generated training examples. The run completed on 21 August 2026. This post revisits that existing result; it isn’t announcing a new training run.
Compare what changed
The saved evaluation contains before-and-after predictions for the same 30 test messages.
Model
Requests routed correctly
Before training
23 / 30
After training
30 / 30
That is seven additional correct routes in this test. Both versions returned a valid team name for all 30 messages, so the change here is in choosing the recorded destination.
I checked those counts against the saved predictions. I did not rerun inference for this article.
How to read this result
This is a small synthetic workflow demonstration, not a customer benchmark. Thirty generated messages cannot establish production accuracy or a saving on a customer’s bill.
The evaluation rows also participated in checkpoint evaluation. There was no separate blind test, and I have not independently re-audited overlap between the training and evaluation message patterns. The full training protocol matters when interpreting a result this small.
There was also no comparison with a simple classifier in this run. Improving a language model does not establish that it is the best tool for the task. Rules, a classifier or better prompting may be enough.
Where Farka fits
The part I want Farka to make easier is that comparison loop. Start with a task you can describe and examples you have permission to use. Keep a meaningful test separate. See whether training helps before deciding to use the model.
For a real workflow, I would want a larger, independently held-out test, realistic mistakes and a simpler baseline before making a quality or cost claim.
]]>Edi HasajPaseo Changed Everything About My Multi-Account Codex Setup2026-08-09T00:00:00+00:002026-08-09T00:00:00+00:00https://edihasaj.com/posts/paseo-changed-my-multi-account-codex-setupI had just finished building a Codex Account Switcher.
It solved a real problem. I use two Codex accounts, one for work and one for personal projects. On macOS, running both official desktop profiles at the same time requires two isolated state directories, two Electron data directories, and a small controller to keep the Dock sane. I built the controller, documented the setup, released it, and thought the system was finished.
The account switcher was still correct, but it was solving the problem one layer too high.
The switcher manages app windows. Paseo manages the agents themselves.
That distinction changed my setup from two desktop applications I had to keep alive into a small, persistent agent infrastructure spread across my MacBook and Mac Studio.
What Paseo actually is
Paseo is an open-source control plane for coding agents. It does not replace Codex, Claude Code, Copilot, OpenCode, or the other tools it supports. It launches the native agent CLIs already installed on your machine, using their existing credentials, configuration, skills, and tools.
A local daemon owns the agent processes. Desktop, mobile, web, and CLI interfaces connect to that daemon as clients.
That architecture sounds like an implementation detail. In practice, it is the entire point:
closing a client does not redefine where the work lives;
the execution machine keeps its own code, credentials, and toolchain;
another client can reconnect and continue controlling the same agents;
multiple providers and multiple profiles of one provider appear in one interface;
workspaces, terminals, services, schedules, and agent lifecycles share one supervisor.
Paseo is closer to Docker’s daemon-and-client model than to another chat window. The UI is useful, but the daemon is the product.
The setup I ended up with
I now run Paseo in two places for two different jobs.
Layer
MacBook
Mac Studio
Role
Interactive local work
Always-on execution host
Daemon
Started by the Paseo desktop app
Headless CLI daemon managed by launchd
Network
Bound to loopback
Bound only to its Tailscale address
Remote relay
Disabled
Disabled
Codex profiles
Work and personal
Work and personal
Client access
Desktop and CLI
Desktop, CLI, or mobile over Tailscale
The MacBook setup is deliberately simple. Opening Paseo starts its bundled daemon on 127.0.0.1:6767. Local clients talk to it over loopback.
The Studio is the durable half. Its Paseo daemon starts at login under a user LaunchAgent with RunAtLoad and KeepAlive. The service listens on the Studio’s private Tailscale address, not 0.0.0.0, and the public relay is disabled. A health endpoint gives me a boring test that the daemon is reachable before I blame a client.
The practical result is that the MacBook can be the steering wheel without being the engine. Long-running work can live on the Studio, where the repositories, compilers, authenticated CLIs, and background services already exist.
Two Codex accounts become two providers
This is the part that made my account-switching workaround feel suddenly small.
Paseo supports custom provider profiles. A profile can extend the built-in Codex adapter and add environment variables. I point each profile at a different CODEX_HOME:
Paseo now shows both accounts as first-class choices. Selecting one launches the same native Codex binary with the corresponding home directory. No logout, no token copying, no wrapper flag, and no second Electron process.
It also preserves the boundary I care about:
Shared deliberately
Kept separate
config.toml
auth.json
AGENTS.md
sessions
hooks
history and logs
prompts and rules
local databases
skills
account usage and limits
On both machines, the secondary Codex home links back to the primary profile’s configuration, instructions, hooks, prompts, rules, and skills. Authentication and operational state remain real files inside each account directory.
That gives me one operating policy with two identities. A correction to an agent rule or a new skill reaches both profiles, while credentials and session history never cross the boundary.
Do not symlink auth.json between profiles. The point is shared behavior, not shared identity.
Persistence is the larger unlock
My desktop switcher kept both Codex applications open, which was enough for local multitasking. It still depended on GUI processes, a logged-in desktop session, and the health of two Electron instances.
Paseo moves process ownership to the daemon and its supervisor. On the Studio, launchd keeps the daemon available. Paseo owns the agents, records their state, and exposes the same lifecycle through every client.
I can start an agent from the MacBook, check it from a phone, send a follow-up through the CLI, and return to the desktop timeline later. The agent still runs where the repository and tools live: on the Studio.
This is a much cleaner mental model:
MacBook / phone / CLI
          |
       Tailscale
          |
   Paseo daemon on Studio
      /             \
Codex Work     Codex Personal
      \             /
 shared tools and project policy
 separate auth and session state
The clients are replaceable views. The daemon is the durable owner. The execution host is the source of truth.
It is more than remote control
Remote control got my attention. Orchestration is what makes Paseo more ambitious.
An agent can use Paseo to discover configured providers, create an isolated worktree, launch another agent, send follow-up prompts, and keep the resulting work visible in the same application. A Codex parent can delegate to Claude, or the reverse. Paseo also exposes scheduled agents, heartbeats, supervised workspace scripts, terminals, and services.
Native subagents are still useful. They are fast and tightly integrated with one provider. Paseo subagents solve a different problem: lifecycle and workspace ownership across provider boundaries.
The worktree support matters here. Two agents editing the same checkout are still two processes racing over the same files. A control plane cannot repeal Git. Paseo-managed workspaces give parallel tasks separate branches and directories instead of asking everyone to behave carefully in one working tree.
What happened to the account switcher?
I removed it from both machines.
The two-profile macOS setup remains useful for anyone who needs the official Codex desktop experience for both accounts. It handles Electron profile isolation, focus switching, and the Dock. Paseo does not turn the official app into a multi-account app.
But I no longer need two official desktop processes as my control plane. Paseo gives both identities named provider profiles and keeps their agents under one supervised lifecycle. The switcher did its job, but the daemon made it unnecessary in my setup.
My default model is now:
Codex identities live in separate CODEX_HOME directories.
Shared rules and skills are linked explicitly.
Paseo exposes each identity as a named provider.
A local daemon handles laptop work.
A persistent Studio daemon handles long-running work.
Tailscale provides the private path to the Studio.
Desktop, mobile, and CLI clients attach to the daemon that owns the task.
That model scales beyond two accounts and beyond Codex. The provider is a launch contract. The daemon is the lifecycle owner. The client is just where I happen to be looking.
Security boundaries I kept
An always-on agent daemon can execute code with the permissions of its user. Treat it like infrastructure.
My setup follows a few rules:
no daemon bound to every network interface;
no public port forwarding;
direct Studio access only across Tailscale;
the hosted relay disabled because I do not need it;
provider credentials left in the native provider homes;
no auth files copied into Paseo configuration;
a dedicated non-root user context;
exact host allowlisting and a small health check;
regular Paseo updates while the project is moving quickly.
Paseo’s relay is end-to-end encrypted and open source, so disabling it is a topology choice, not a claim that it is unsafe. For a direct network binding, Paseo also supports password authentication. I would add that defense even on a private VPN when the daemon is shared by several devices.
The honest limitations
Paseo does not merge accounts, chats, billing, or usage limits. It gives each profile a clean launch path.
It does not make unsafe agent permissions safe. If a Codex profile has broad filesystem and network access, launching it through Paseo preserves that power.
It does not make one checkout safe for parallel edits. Use worktrees.
It also does not remove the need to understand where state lives. PASEO_HOME owns Paseo state. Each provider still owns its own credentials and sessions. Repositories still live on the execution host.
Finally, Paseo is young and changing quickly. I am comfortable running it because the architecture is local-first, the code is public, the underlying CLIs remain usable without it, and my account isolation does not depend on a proprietary cloud database.
The real change
I started with a UI problem: how do I keep two Codex accounts open on one Mac?
The better question was: who should own the lifecycle of my agents?
Once the answer became “a daemon on the machine doing the work,” the rest simplified. Multiple accounts became provider profiles. The Studio became an execution host. The MacBook and phone became clients. Persistence stopped depending on a window staying open. Orchestration became possible without replacing the tools I already use.
The account switcher fixed my Dock. Paseo made me stop needing the switcher.
Paseo changed the system.
Frequently asked questions
Can Paseo run multiple Codex accounts?
Yes. Define multiple custom providers that extend Codex and give each one a different CODEX_HOME. Each profile uses its own Codex authentication and state.
Does Paseo replace Codex?
No. It launches and supervises the native Codex CLI. Your installed binary, subscription, configuration, skills, MCP servers, and credentials remain yours.
Will work continue if I close the desktop app?
The daemon owns the agent lifecycle, not the desktop window. Keep the daemon and execution host running. Another Paseo client can reconnect to it later.
Why use a Mac Studio daemon instead of SSH alone?
SSH gives me a shell. Paseo adds durable agent lifecycle, reconnectable timelines, named providers, mobile and desktop clients, orchestration, workspaces, schedules, and supervised services.
Is the Paseo relay required?
No. Paseo supports direct connections. I use a Tailscale-only address and disable the relay. The official relay is an alternative for simpler remote access and provides end-to-end encryption.
Do I still need the Codex Account Switcher?
Not for my current workflow. I removed it from both machines. It is still useful for simultaneous use of two official Codex desktop profiles because Paseo handles native CLI agents and their lifecycle, not Electron profile isolation inside OpenAI’s app.
]]>Edi HasajHow to Run Two Codex Accounts on macOS with Separate Profiles2026-07-26T00:00:00+00:002026-08-01T00:00:00+00:00https://edihasaj.com/posts/two-codex-accounts-two-dock-icons-macos
Update, August 1, 2026: The original version used two pinned wrapper apps.
That looked tidy until macOS created extra running-app tiles and Spotlight found
old launcher copies. The improved setup keeps one official Dock icon and uses
a menu-bar controller to open or focus either isolated account.
The result is practical multitasking without modifying the signed Codex app:
Option-Command-1 opens or focuses Primary;
Option-Command-2 opens or focuses Secondary;
switching focus does not quit the other process;
Open Both starts both profiles;
Quit Primary and Quit Secondary stop them explicitly;
Applications and Spotlight contain only the current controller and launchers.
How the two profiles are isolated
Profile state
Primary
Secondary
Codex configuration and authentication
~/.codex
~/.codex-work
Desktop application data
normal app data
~/Library/Application Support/Codex Second
CODEX_HOME isolates Codex configuration and authentication. The separate
--user-data-dir is also required because the desktop app uses Electron and
otherwise hands a second launch back to the first process.
Test the secondary account
Run this in Terminal before installing the switcher:
codex_app="/Applications/ChatGPT.app"[[-d"$codex_app"]]||codex_app="$HOME/Applications/ChatGPT.app"mkdir-p"$HOME/.codex-work"mkdir-p"$HOME/Library/Application Support/Codex Second"
open -n"$codex_app"\--env"CODEX_HOME=$HOME/.codex-work"\--args"--user-data-dir=$HOME/Library/Application Support/Codex Second"
A second Codex window should open. Sign into the other ChatGPT account once;
later launches reuse that profile’s isolated authentication and desktop state.
If swiftc is unavailable, install Apple’s Command Line Tools first:
xcode-select --install
The installer:
leaves /Applications/ChatGPT.app unchanged and preserves its signature;
installs ~/Applications/Codex Account Switcher.app as a login item;
installs background launchers named Codex Primary, Codex Secondary, and
Codex Open Both in ~/Applications;
keeps exactly one official ChatGPT/Codex Dock pin;
removes stale launcher pins that cause duplicate running-app tiles;
moves replaced launchers to the Trash so they remain recoverable.
The three Applications launchers signal the menu controller and immediately
exit. Because they are background agents, they do not create their own Dock
tiles. They are useful from Finder, Launchpad, Raycast, or Spotlight.
Multitask without stopping background work
After installation, choose Open Both or open the two profile launchers.
Both desktop processes remain alive. Option-Command-1 and
Option-Command-2 only change focus; they do not terminate either account.
That means a local task can continue in the background while you work in the
other account. Keep the Mac awake and leave both processes open. A Codex crash,
manual quit, restart, or system sleep can still interrupt local work.
When you want to reduce memory use or avoid running two instances, use
Quit Primary or Quit Secondary from the menu-bar controller.
Keep the Dock clean
Pin only the installed OpenAI app. Do not pin Codex Primary,
Codex Secondary, or Codex Open Both.
Both Codex processes share the same signed bundle identity. Depending on the
macOS version and current Dock state, macOS may group them under the official
tile or temporarily show another running tile. Pinning wrapper apps cannot
reliably force two permanent identities and is what causes the confusing
duplicate-icon behavior.
Verify both accounts
Choose Open Both, then run:
pgrep -alf"ChatGPT.app/Contents/MacOS/ChatGPT"
You should see two main processes. The secondary process includes:
--user-data-dir=/Users/you/Library/Application Support/Codex Second
Each window should remember its own account after quitting and reopening. Do
not place either profile directory in a repository or public sync folder. This
setup isolates local profiles; it does not merge chats, projects, billing, or
usage limits.
Frequently asked questions
Can I run two Codex accounts at the same time on one Mac?
Yes. The signed app runs twice, while the second process uses an isolated
CODEX_HOME and Electron user-data directory.
Why is CODEX_HOME alone not enough?
It separates Codex configuration and authentication, but not all Electron
desktop state. The separate user-data directory allows the second desktop
process to start independently.
Can both accounts keep working while I switch windows?
Yes. The switcher opens or focuses the requested profile and leaves the other
one running. Use the explicit Quit menu items when you want to stop one.
Why not pin two custom Codex launchers?
The launchers and real running app have different identities, while both real
Codex processes share OpenAI’s bundle identity. macOS therefore cannot map two
custom permanent pins cleanly to the two processes.
Does this modify the installed Codex app?
No. The official bundle is neither edited nor re-signed. The installer only
builds and signs the small local controller and its background launchers.
Is this guaranteed to be crash-free?
No. Separate profile directories prevent state collisions, but simultaneous
desktop instances remain a local workaround. Use one process when maximum
stability matters.
]]>Edi HasajAnthropic Pulled Fable. Build Your Own Intelligence.2026-06-13T00:00:00+00:002026-06-13T00:00:00+00:00https://edihasaj.com/posts/anthropic-pulled-fable-build-your-own-intelligenceAnthropic launched Claude Fable 5 on June 9. Three days later, on June 12, they turned it off. Not for one region, not for one customer tier, for everyone on the planet at once. Fable 5 and Mythos 5, gone, the same week they shipped.
This was not a safety rollback or a capacity problem. The US government issued an export-control directive under national security authorities barring any foreign national from accessing the models, whether they sit inside or outside the United States, including Anthropic’s own foreign-national employees. There is no clean way to comply with an order like that while keeping a global product live, so Anthropic did the only thing the order left them: they pulled the plug for everybody. Every other Anthropic model stayed up. Only the two most capable ones went dark.
The cited reason is the interesting part. According to Anthropic, the directive leaned on the fact that Fable 5 was unusually good at finding software vulnerabilities. That is the whole story in one line. A model crossed a capability threshold where a government decided it was a weapon, and weapons do not get exported.
the thing nobody priced in
Most of the AI conversation for the last two years has been about capability. Can it code, can it reason, can it use a computer, can it replace a junior. We argued about benchmarks and pricing and context windows. We did not spend nearly enough time on a much simpler question. Who can turn it off, and when.
Now we have the answer, with a date on it. June 12, 2026. Frontier intelligence is no longer just a product you rent. It is a strategic asset that a single government can revoke overnight, retroactively, after you have already built on top of it. Your roadmap, your agents, your internal tooling, all of it sitting on an API that a directive can switch off before lunch.
If your company is outside the US, this is not hypothetical anymore. The most capable American models are now legally off limits to you, not because of price or availability, but because of your passport. That is a hard constraint, and it does not negotiate.
this is the start, not the exception
It is tempting to read this as a one-off. A single tense week, a single model, a policy that gets walked back once the lawyers calm down. I do not think that is what is happening.
The pattern underneath is durable. Models keep getting better at exactly the things states care about most, which is finding vulnerabilities, writing exploits, moving through systems, and reasoning about targets at scale. The better they get at those things, the more they look like dual-use technology, and dual-use technology gets export controls the same way chips and crypto and centrifuges did. Fable 5 is the first frontier model to hit that wall in public. It will not be the last. Expect more directives, more sudden suspensions, more capability tiers that quietly become classified by function.
So the intelligence war stops being a metaphor about labs competing on benchmarks. It becomes a literal one between countries, fought over who can build, run, and gate the smartest systems, and who is left renting access that can be cancelled.
the lesson is sovereignty
Here is where it lands for me. If intelligence is now a national asset that can be switched off, then every serious country, and frankly every serious company, has to treat the ability to produce its own intelligence as infrastructure. Not a nice-to-have, not a research vanity project, infrastructure on the level of power and water.
This is not a fringe take anymore. More than 60 nations have published formal AI strategies, and over 30 have put real money behind building domestic capability. Jensen Huang said it plainly at Davos in January: every country should build its own AI, on its own infrastructure, trained on its own language and culture, with its national intelligence as part of its own ecosystem. France has Mistral. India is shipping models tuned for Hindi, Tamil, and the rest. Saudi Arabia is pushing HUMAIN. Brazil committed billions to a sovereign plan with its own supercomputer. There is a 720 million dollar build-out putting AI factories across Africa for data sovereignty. The world already started moving, and the Fable suspension just proved why.
Sovereign AI is the unglamorous version of independence. It means your own compute, your own data, your own talent, your own governance, and crucially your own weights that no foreign directive can revoke. The country or company that owns the stack gets to keep thinking when the export controls come down. The one that rents it gets a 503 and a press release.
what i would actually do
I am not saying every startup needs to train a frontier model. That is a fantasy and a good way to burn your runway. But the strategic posture has changed, and the cheap moves are obvious now.
Stop building your core on a single provider you cannot control. Keep capable open-weight models in your stack, the ones you can run yourself on hardware you can point at, so that when an API goes dark you degrade instead of dying. Treat model access the same way you treat any other dependency that a government could sanction, which means assume it can disappear and design so that it disappearing is survivable. And if you are operating at the level of a country, the calculus is even simpler. Own the compute, fund the labs, keep the weights at home, because the alternative is letting someone else decide when your economy gets to be smart.
Fable 5 was a great model. For three days. The model is not the point. The point is that the smartest tools on earth are now things states will take away from you the moment they decide you should not have them, and the only durable answer to that is to build your own. 2026 is the year that stopped being a slogan and became a survival requirement.
The patch, as always, is our job. So is the intelligence.
]]>Edi HasajUniversal Memory Protocol: Simple Agent Memory That Moves2026-06-07T00:00:00+00:002026-06-07T00:00:00+00:00https://edihasaj.com/posts/universal-memory-protocol-simple-agent-memoryI built Recall because I was tired of correcting coding agents about the same repo rules every week. That solved a local problem. The agent would remember “use pnpm here”, “run this gate before handoff”, “do not touch this folder”, and the next session would start with that context already loaded.
Then I hit the next problem.
The memory was useful, but it was trapped in one shape. Claude Code had one way to hold project rules. Codex had another. ChatGPT had another. Local agents had files. Some frameworks had vector stores. Some had graph stores. Some had nothing. Every tool was learning the same things about me and my projects, but none of them could share those memories in a clean way.
MCP lets agents use tools. A2A lets agents talk to agents. UMP lets agents carry memory.
It is not meant to be a new database. It is not meant to replace Recall, Mem0, Letta, Zep, Obsidian, Postgres, SQLite, Redis, or a vector index. It is the small contract between them.
The Shape
UMP is deliberately small:
A portable memory record.
Six core operations.
MCP, HTTP, and file bindings.
Conformance levels from simple export to full signed runtime.
The record is the main thing. A memory needs a type, a body, a scope, time fields, lifecycle hints, relations, provenance, consent, and integrity.
In normal words:
what is this memory, who owns it, where is it valid, when was it true, where did it come from, who may see it, and can I verify it?
That sounds obvious, but most agent memory today does not carry all of that. It might have text and an embedding. It might have a user id. It might have a timestamp. But the moment you try to move it from one agent or store to another, the missing fields matter.
If a memory says “use pnpm”, is that global, repo-specific, team-specific, or only true for one branch? If it says “the deployment target is staging”, was that true yesterday or is it true now? If an agent wrote it, did the user approve it? If it contains a secret or personal detail, should it be exported at all?
UMP puts those questions into the record instead of leaving them as product-specific behavior.
How I Came To It
The first version of the idea came from pain, not architecture.
I use multiple agents. I switch between tools. I also work across enough repos that the same mistake keeps coming back in different clothes. One agent learns a rule, another agent does not know it, and I become the bridge.
Recall proved the useful part: corrections can become repo memory, memory can be ranked, stale memories can be retired, and the agent gets better without a giant instruction file.
But Recall also made the protocol gap obvious. The useful abstraction was not “Recall”. It was:
an agent needs to ask for relevant memory, write new memory, revise old memory, forget unsafe memory, and prove where memory came from.
That maps cleanly to operations:
Operation
Meaning
capabilities
What does this memory server support?
recall
Find relevant memories for this scope and query.
remember
Store a new memory.
get
Fetch a memory by id.
revise
Replace a memory without destroying its history.
forget
Tombstone or remove a memory with a reason.
That is enough for a small client. It is also enough for adapters. A fancy graph memory system and a simple JSON file can speak the same verbs, while still behaving differently underneath.
What It Fixes
UMP fixes four practical problems.
First, memory lock-in. If Claude learns a project rule and Codex cannot read it, that is not memory. That is product state. UMP makes the memory record portable so it can move between hosts and stores.
Second, stale memory. A lot of memory systems overwrite facts. That is dangerous because old context disappears and the agent cannot reason about when something was true. UMP uses bi-temporal records and supersession. A memory can be replaced without pretending the old one never existed.
Third, trust. Recalled memory is not sacred. It can be wrong, stale, malicious, or out of scope. UMP treats memory as untrusted input and requires safe rehydration before it enters the model context. The context block says, in effect, “these are references, not instructions.”
Fourth, ownership. A useful memory record should carry provenance, consent, and eventually signatures. UMP uses existing standards where they fit, like W3C PROV for provenance, DID for owner identity, and RFC 8785 JSON canonicalization for deterministic signing.
The important point is what UMP does not try to fix. It does not decide which embedding model is best. It does not mandate graph search. It does not freeze a decay curve. It does not tell Recall, Zep, Letta, Mem0, SQLite, or Postgres how to rank memory.
It standardizes the parts that must match for memory to travel. The intelligence stays inside the engine.
How It Runs
The fastest way to use it is through MCP, because most agent hosts already know how to talk to MCP servers.
That gives the host ump.recall, ump.remember, ump.get, ump.revise, ump.forget, and ump.capabilities.
By default, the reference server writes a portable file at:
~/.ump/memory.ump.json
Point another MCP host at the same store and it can use the same memories. That is the money shot: write in one agent, recall in another.
There is also an HTTP binding for apps that do not speak MCP, and a file binding for plain exports. That matters because adoption should not require the full runtime. A project can start at L0 with a *.ump.json or *.ump.md file, then move to an L1 or L2 server later.
How Fast It Is
For the default local file store, the answer is boring and good: around 5ms recall at 3,000 records in the current benchmarks. That is the right default for most project memory. It is local, portable, and fast enough that the agent does not feel like it is waiting on a separate brain.
The richer Recall-backed path costs more because it does actual semantic retrieval. In my current benchmark notes, it is roughly 100ms to write and roughly 200ms to recall after warming the local embedding model. The tradeoff is quality: paraphrase top-1 recall improves from 1 out of 8 with lexical matching to 5 out of 8 with Recall’s vector plus BM25 search.
So the rule is simple:
Store
Best for
Rough speed
JSON file
portable local memory, repo rules, simple preferences
about 5ms recall at 3k records
Markdown files
human-editable memory
depends on folder size
Recall adapter
semantic search and stronger retrieval quality
about 100ms write, about 200ms recall
Vector store
scale and semantic recall
depends on embeddings and backend
Fast memory is useful because agents ask for memory often. But retrieval quality matters too. UMP keeps that choice open. You can start with the file store, then swap the backend when the shape of the work needs it.
The Part I Care About
The part I care about is not that UMP exists as a spec. Specs are cheap.
The part I care about is the round trip:
an agent writes a memory, another agent recalls it, the record is still owned by the user, and the receiving agent treats it as scoped reference data instead of hidden instruction text.
That is the missing piece for serious agent work. Agents are getting better at tools through MCP. They are getting better at coordination through A2A. But they still forget, fork, and trap memory inside product-specific state.
I do not want every new agent to start from zero. I also do not want all my working memory locked inside one vendor.
UMP is my attempt to make the layer small enough to adopt and structured enough to trust.
One record. Six operations. Memory that moves.
]]>Edi HasajEverything Will Be Agent Use2026-05-14T00:00:00+00:002026-05-14T00:00:00+00:00https://edihasaj.com/posts/everything-will-be-agent-useI have been watching the new wave of computer-use agents and honestly, most of what they do is incredible. The mouse moves like a real user. Forms get filled. Sites get navigated. Tabs get juggled. Tasks that needed a person sitting in front of a screen are now running on their own, end to end, with surprisingly little hand-holding. Five years ago this was science fiction. Today it is a demo you can run on your own laptop, and the future of how we use software clearly runs through here.
Then you watch long enough and the same shape keeps showing up. The agent looks great for the first half of the task, sometimes the first ninety percent, and then the workflow hits a login wall, a captcha, a 3-D Secure popup, a card form that wants a human phone tap, and everything stalls. The agent was good enough to make the stall feel absurd. That is new. A year or two ago the impressive part was that it could move through the task at all.
That is the actual story of computer use right now. Agents got useful faster than the systems around them got ready to trust, verify, and bill them.
the cursor is the new interface
For a few years we assumed AI would live in a chat box. Type, answer, repeat. The interface was words.
That assumption is dead. The interface is your operating system now. The agent gets the mouse, the keyboard, the browser tabs, sometimes your card. It does not describe how to do the thing. It does the thing.
Every serious lab is on this. Anthropic shipped computer use in late 2024, and Claude has been driving desktops since. OpenAI followed with Operator. Google has Gemini computer use plus Project Mariner inside Chrome. Perplexity built Comet, an entire browser shaped around an agent. Manus came out of China with a general-purpose agent that books trips, files paperwork, and scrapes whatever you point it at. Microsoft and Apple are wiring this into the OS itself, quieter, slower, much closer to where the real leverage is.
Pick any of them. The message is the same. The agent is the new user.
how far we actually got
Two years ago, asking a model to complete a real multi-step task on a real desktop was a coin flip at best. OSWorld, the most honest early benchmark for desktop agents, was sitting at around 14% when it launched in 2024. The progress since has been fast enough that any single number starts going stale almost immediately.
On “can the agent see and click the right thing”, the field is getting very good. Pixel-grounding benchmarks like ScreenSpot are above 90% for the top models. The eyes work. The hands mostly work. The old joke that agents cannot use computers is aging badly.
On “can the agent finish a real workflow”, the answer is messier. The best systems are now brushing against human baselines on OSWorld-style tasks, which is a ridiculous improvement from 2024. But benchmark parity is not the same thing as operational trust. Newer cross-application evals still show ugly failure rates once the task requires several apps, conditional judgment, cleanup, and persistence. Even a 75% task success rate means one in four things still falls over somewhere.
And that “somewhere” is almost never “I could not read the button”. It is the page reloaded, the login screen came back, a captcha appeared, a popup blocked the click, the cart wants your card, or the agent did the right local action inside the wrong global state.
The cursor is not the bottleneck. The world around the cursor is.
the five shapes people are shipping
There is a tendency to talk about “computer use” like it is one product. It is at least five, and the shapes have very different trade-offs.
The desktop agent runs on your machine and can touch anything you can touch. Anthropic’s computer use sits here. Max power, max blast radius. If it gets confused, it can delete things you cared about. Trust bar is high. Best for power users and developers who can sandbox it.
The browser agent lives inside a tab. Perplexity Comet, Arc’s agent, the various Chromium-based experiments. Safer becuase the world it can break is small, but it hits a wall every time a workflow leaves the browser. Try to download a PDF, sign it, attach it back somewhere, and the seams show up immediately.
The managed agent runs in the cloud. OpenAI Operator is the cleanest example. Convenient because you do not give it your laptop, but the moment the site you care about decides cloud IP’s look like bots, you are stuck in captcha purgatory.
The OS-level agent is the long game. Apple, Microsoft, and Google’s mobile push are all trying to wire agents into the system itself: real accessibility trees, real intents, real content types. When the OS exposes structure, the agent stops guessing. This is also the lane with the most patience, which is why Apple in particular looks slow untill they suddenly are not.
The generalist agent is the demo champion. Manus, Mariner-style long-horizon planners. They will plan your trip, file your form, scrape your competitor. They will also confidently do the wrong thing for ninety steps before failing in a way you cannot easily unwind.
Each shape is real. None of them is finished.
where the workflow actually breaks
If you sit and watch a serious computer-use demo end to end, the failure mode is almost always the same. The agent looks brilliant for the first half of the task and then loses to something boring.
It is not glamorous. Finding the product is easy. Adding it to the cart is easy. Then auth shows up, fraud signals trip, a phone-based 3-D Secure challenge fires off, and the agent stalls because the verification was designed to assume there is a human holding a phone, not a long-running automation.
Most demos quietly stop right before this cliff. The honest ones hand control back to the user at checkout, which kind of defeats the point of an agent.
the protocols are the actual story
The reason buying is so painful is structural. The stack assumes a human in a browser, with cookies, a card on file, a phone for 3-D Secure, and a fraud score built from device fingerprints and behavior. An agent breaks almost every one of those assumptions, and the merchant has no clean way to know “this purchase was authorized by Edi, with these limits, through this agent, for this purpose”. So they either block it, or they let it through and hope.
This is what protocols are quietly fixing. Three layers matter.
MCP is the floor. It is the boring, beautiful plumbing that lets an agent talk to a tool, a database, a file system, an API in one standard way. It is already widely adopted across Anthropic, OpenAI, Cursor, and most serious IDEs. If you are building anything agentic, MCP is the layer you build on, not around.
A2A is the layer above. Google and a coalition of partners pushed it out in 2025 as an open protocol for agents from different vendors to talk to each other. My booking agent calls your inventory agent, they negotiate, work happens, result comes back. If A2A actually catches on, the web stops being a pile of HTML that an agent has to squint at, and starts being a network of cooperating services with structured handshakes.
AP2 is the one I find most concrete. The Agent Payments Protocol, announced by Google with Mastercard, American Express, Coinbase, PayPal and a long list of issuers in late 2025, is an attempt to do for agent commerce what 3-D Secure tried to do for online cards. The agent presents a verifiable mandate signed by the human. The merchant verifies it. The issuer verifies it. Payment flows, with cryptographic evidence at every step. “This agent bought this item for this user with this budget” finally has a real signature behind it instead of a session cookie and a prayer.
If you are a merchant, this is the upgrade path you cannot ignore for long. Either you wire up agent-friendly payments with verifiable mandates, or you start quietly blocking a non-trivial slice of your traffic, because that slice is no longer human.
the messy middle is where we live
The bad news is that none of these protocols are live across the long tail. MCP is the closest. A2A is real but mostly between cooperative parties. AP2 has the right names on the press release and nowhere near enough merchant support to run your week through it yet.
So agents in 2026 are stuck doing two jobs at once.
That is why the moment feels so strange. Agents are good enough to use every day, and not good enough to forget about while they hold your card, your calendar, your inbox, or your company account.
One job is helping the long tail of legacy sites and apps that will never speak A2A by pretending to be a human. This is a perception and resilience problem. Better screen understanding, better recovery when a popup appears, better memory of “I already tried this and it failed”. The flashy demo lives here, and so does most of the brittleness. Every UI redesign quietly breaks an agent somewhere.
The other job is helping the leading edge of services adopt MCP, A2A, AP2, so the next round can be cleaner. This is mostly a trust and identity problem. Who signed the mandate, who is liable, how do we revoke, what audit trail do we keep. Less glamorous. Much more durable.
The winners over the next few years will not be the labs with the flashiest demo. They will be the ones that solve the perception problem and the trust problem at the same time, so the agent is both capable of running a task on a legacy site and credible enough to do it on a modern one. Most of the current crop is good at one and pretending about the other.
what to actually do
If you build software, four things are worth doing this year. Design your UI so an agent can also use it: real accessibility trees, structured labels, predictable flows, not just whatever the design system spat out. Ship an MCP server if you have any tool surface worth exposing. Start thinking about an A2A integration even before you build it, because the shape of your data and identity model matters more than the wire format. If you take payments, track AP2 and similar mandates, even if you do not implement yet, because the fraud and identity decisions you make in 2026 will determine whether you can adopt cleanly in 2027.
If you do not build software, the practical version is shorter. The next few apps you install, ask whether an agent could run it for you. If yes, thats your new productivity ceiling. If no, that is a future migration waiting to happen.
The cursor is moving. Whether it is moved by you or by something acting on your behalf is going to become a question you ask several times a day. I am not nostalgic about clicking through forms. I am, however, nervous about the gap between what these agents can already do and what the systems on the other side are ready to verify, trust and bill. That gap is the work of the next two years, and the companies that close it first are going to look very different from the ones currently winning the demo cycle.
The demo is the easy part. The plumbing under it is the rest of the decade.